Building a Modular Monolith
A practical guide to a modular monolith in Kotlin and Spring Boot: where to draw the boundaries, how to make the build enforce them, how modules talk, and how a checkout survives a failure halfway through.
View Example on GitHub: complete source code in Kotlin + Spring Boot
Contents
- Intro: The Coupling Problem
- How Much of This You Need
- Part 1: Where to Draw the Lines
- Part 2: Enforcing the Lines
- Part 3: Inside the Modules
- Part 4: Isolating Data
- Part 5: Module Communication
- Part 6: Processes Across Modules
- Part 7: Errors and Validation
- Part 8: Facing the Outside World
- Part 9: Testing
- Part 10: Putting It All Together
- Part 11: One Domain, Several Products
- Part 12: Building With Coding Agents
- End: Conclusion and Cheat Sheet
Introduction
Most backend codebases don’t start broken. They start small, coherent, and easy to change. Then time passes.
Features ship. Teams grow. Deadlines happen. And one day you realize that changing the checkout flow requires touching seven packages, three shared utilities, and a database table that four other features depend on. You’re not sure what will break, so you test everything manually and deploy on a Friday afternoon with your finger hovering over the rollback button.
This is two problems working together. Low cohesion: related code is scattered across the codebase instead of living together. High coupling: unrelated modules depend on each other’s internals, so changes ripple outward in unpredictable ways.
When it gets bad enough, teams usually respond in one of two ways.
Some reach for microservices. Split everything into separate services. Nothing can import anything directly anymore, so the code can’t tangle. The coupling doesn’t go away, though: it moves into the network, and plenty of teams end up with a distributed monolith, services that still have to change and deploy together. And it trades code complexity for operational complexity: network failures become normal failures, data consistency requires careful choreography, and “running locally” becomes a research project. You wanted to fix your architecture and accidentally became a distributed systems team.
Others try better discipline. Add architectural guidelines. Improve folder structure. Be more careful in code review. This is cheaper and less disruptive, but discipline erodes. Someone imports an internal class because it’s convenient. Someone adds a “temporary” dependency to meet a deadline. Guidelines without enforcement are aspirations.
A modular monolith is a way to make the second approach actually stick. It’s a monolith where boundaries are enforced by the build system, where you can’t import another module’s internals because the compiler won’t let you.
You keep the operational simplicity of a single deployable. But you get real architecture: explicit contracts between modules, isolated data, and the ability to change one module without accidentally breaking others. When something goes wrong at 3am, there’s one service to check, one log to read, one thing to restart.
This guide is a practical walkthrough of building one in Kotlin and Spring Boot, at the scale most of us actually work at: one team or a handful, thousands or millions of users rather than hundreds of millions. It follows one example, a small web shop, from its first boundaries to a checkout that survives a failure halfway through, and on to a second product built on the same domain. Everything in it comes from building systems this way, not from a whiteboard.
How Much of This You Need
This guide can read like a checklist: do all of it, or you’re doing it wrong. That’s not how it’s meant. Every piece of structure costs something, and should earn that back by taking away a pain you actually have. Some things are cheap on day one and very expensive later: once two modules share a table, separating them is a project. Others are cheap to add the moment you need them, and only weigh you down before that.
So here’s the dial. The left side is what I’d do from the first commit, however small the project. The right side is the rest, with the moment it starts paying for itself.
From day one
- Modules around business capabilities, not technical layers (Part 1)
- A one-way dependency graph between them, checked by a test or the build (Part 2)
- A database schema per module, with no foreign keys between them (Part 4)
- Events stored in an outbox, for anything you can't afford to lose (Part 5)
- Expected errors as values in each module's contract (Part 7)
- Tests per module, against a real database (Part 9)
Once it starts to hurt
- Several teams, agents writing much of the code, or a test-time check that comes too late
- Separate Gradle modules for contract and implementation (Part 2)
- A query reaches into another module's schema
- A database role per module (Part 4)
- A screen sorts or pages by another module's data
- A read model (Part 4)
- One business operation changes several modules
- A process on the order, with reservations and timeouts (Part 6)
- Pages that combine several modules, or clients you don't deploy yourself
- A storefront module, and public API models of their own (Part 8)
- A second product needs the same domain
- A shared domain with its own language, scopes and SPIs (Part 11)
- Complex domain logic inside a module
- Layers inside that module (Part 3)
- A module has to scale or deploy on its own
- Extract it into a service (Part 10)
Notice what’s on the left: boundaries, data and contracts, which are expensive to change later. The right side is mostly code, which isn’t. Shopify, which runs one of the largest modular monoliths around, came to the same conclusion: the direction of dependencies mattered most, more than hiding each module’s internals.
Starting from an existing monolith? Then you won’t reach zero violations in a week. Record the ones you have, block new ones, and fix the old ones in code you’re changing anyway. ArchUnit’s FreezingArchRule does exactly that.
The rest of this guide describes the whole setup, right side included, so you know where you’re going. You don’t have to build all of it on day one.
Part 1: Where to Draw the Lines
We want boundaries. But where should they go?
Domain-Driven Design has opinions about this. DDD has a reputation for academic terminology and books thicker than your laptop, but ignore all that. The part that matters for architecture is simple: organize around business domains, not technical layers.
Domains, Not Layers
Most backend projects start with a structure like this:
com.example.shop/
├── controllers/
│   ├── ProductController.kt
│   ├── OrderController.kt
│   └── ShippingController.kt
├── services/
│   ├── ProductService.kt
│   ├── OrderService.kt
│   └── ShippingService.kt
└── repositories/
    ├── ProductRepository.kt
    ├── OrderRepository.kt
    └── ShippingRepository.kt
All controllers in one folder, all services in another, all repositories in a third. It feels tidy. It looks professional in code review.
It’s also a mistake.
When you add a shipping feature, you touch files in three different folders. When you want to understand how shipping works, you’re jumping between layers, assembling the picture from scattered pieces. And nothing stops OrderService from calling ProductRepository directly. The folder structure creates the appearance of organization without any actual boundaries.
The alternative is organizing by domain:
com.example.shop/
├── products/
│   ├── ProductController.kt
│   ├── ProductService.kt
│   └── ProductRepository.kt
├── orders/
│   ├── OrderController.kt
│   ├── OrderService.kt
│   └── OrderRepository.kt
└── shipping/
    ├── ShippingController.kt
    ├── ShippingService.kt
    └── ShippingRepository.kt
Now a shipping/ folder contains everything about shipping. New developers can open one folder and understand one capability. Changes stay local. And the structure reveals where real boundaries could be enforced.
The Same Word, Different Meanings
Ask three people in an e-commerce company what “Product” means.
The catalog team says name, description, price, images: it’s what customers browse and search. The warehouse team says weight, dimensions, and whether it’s fragile: they need to put it in a box, not describe it. The inventory team says a product ID and a quantity on a shelf: they don’t care what it looks like.
These aren’t three views of the same thing. They’re three different concepts that happen to share a name. DDD calls this a bounded context: a boundary within which a term has a consistent meaning. You can call it whatever you want. The point is that “Product” means something different depending on who you ask.
The instinct is to create one Product class that serves everyone:
data class Product(
    val id: ProductId,
    val name: String,
    val description: String,
    val price: Money,
    val images: List<Image>,
    val weightGrams: Int,
    val dimensions: Dimensions,
    val isFragile: Boolean,
    val unitsOnHand: Int,
    // ... and it keeps growing
)
One class, no duplication. Efficient, right? But this is how coupling starts. The catalog team adds images; now warehouse code depends on it. The warehouse team adds dimensions; now catalog code carries that weight. Everyone’s afraid to touch this class, and everyone has to.
The fix is recognizing that each context should define its own model:
// In the catalog
data class Product(
    val id: ProductId,
    val name: String,
    val description: String,
    val price: Money,
    val images: List<Image>,
)

// In shipping
data class ShippableItem(
    val productId: ProductId,
    val weightGrams: Int,
    val dimensions: Dimensions,
    val isFragile: Boolean,
)
Yes, you now have two classes that describe the same product. This feels wasteful until you realize the alternative is a God object that grows until it collapses under its own weight. Duplication between contexts is healthy. Duplication within a context is a code smell. Learn the difference.
One Product, Several Owners
Splitting the class is the easy half. The harder half is deciding which context each field belongs to, and the honest answer isn’t always the obvious one.
Take a product’s weight. The obvious home is the catalog: it’s a fact about the product, and the product form already has fifteen fields, so what’s one more? But follow the field around. Who measures it? Someone in the warehouse, with a scale. Who uses it? Shipping, to pick a box and a carrier and to work out the cost. Who notices when it’s wrong? Shipping again, when the carrier sends a surcharge. The catalog might show it on the product page, but no rule in the catalog depends on it.
Udi Dahan has a good phrase for this: a module should be the technical authority for its business capability, owning the data and the rules that go with it. So the question to ask of every field isn’t “what is this a fact about?” but:
Who is allowed to change it, and whose rules depend on it?
Exactly one module should be able to change it. That module owns it. Everyone else asks for it, or keeps a copy. For our product, that gives one ID and three owners:
ProductId("p-42")
- name and description
- images
- price
- status: draft, active, discontinued
- units on hand
- units reserved for orders
- weight
- dimensions
- fragile or not
None of these modules has a Product that knows everything. A page that shows all of it (name, price, “in stock”, “delivered Thursday”) asks all three and puts the answers together. Part 8 shows where that code lives.
A handy rule of thumb: data belongs where it drives a decision, not where it’s displayed. The product page displays the weight; Shipping decides with it.
This isn’t dogma. If your shop sends everything in the same box for a flat fee, nobody decides anything with the weight, and keeping it on the product form is perfectly reasonable. What matters is that it’s a decision rather than an accident. The day Shipping starts calculating with it, move it.
Finding the Right Boundaries
There’s no algorithm for this, but there are useful signals.
Listen for different vocabulary. When warehouse staff say “pick” and “pack” while marketing says “browse” and “wishlist”, you’re hearing two contexts. Language differences usually reflect model differences, and that’s more reliable than most technical heuristics. If you want a structured way to hear them, run an Event Storming session: put the people who know the business in a room, have them write down everything that happens (“order placed”, “parcel picked”, “payment refunded”) on sticky notes along a timeline, and watch where the vocabulary and the people change. Those places are your candidate boundaries.
Different rates of change are another clue. Pricing rules might change weekly; shipping carrier integrations change quarterly. Bundling them means every pricing change risks breaking shipping. And if different people are responsible for different areas, those are natural seams. Conway’s Law isn’t just an observation; it’s a force you can work with instead of against.
Transaction boundaries help too. If two operations almost always happen together in the same database transaction, they probably belong together. If they don’t need transactional consistency, that’s a hint they could be separate. Conversely, if module A makes fifteen calls to module B for every operation, maybe they shouldn’t be separate at all.
Size matters. Can you describe the module in one sentence without conjunctions? “Manages the product catalog” works. “Handles payments and shipping and user profiles” is three modules wearing a trench coat.
Watch out for a few traps. Don’t model from the database up: tables reflect storage decisions, not business boundaries. Don’t slice too thin: you don’t need a separate module for “OrderValidation”, that’s just part of orders. And don’t draw boundaries that cut across team ownership.
The Example We’ll Use
For this guide, we’re building a small web shop with six modules.
Products owns the catalog: names, descriptions, images, prices. Users owns identity and profiles. Payment takes the money, for anything; it knows nothing about orders. Inventory tracks stock, and holds it for orders that haven’t been paid yet. Orders handles purchases, from checkout to delivery. Shipping turns orders into parcels, and owns everything physical about a product: its weight, its size, whether it breaks.
Products, Users and Payment sit at the bottom: they depend on nothing. Inventory depends on Products. Orders depends on all four below it, because it needs prices, customers, stock and payments. Shipping sits on top: it depends on Orders for what to send, and on Products to know which products exist. Nobody depends on Shipping.
Payment at the bottom deserves a word. It would be easy to make it depend on Orders; after all, it’s orders we take payments for. But a payment module that only knows “take this amount, for this reference” can’t get tangled up in how orders work, and it’ll take payments for gift cards next year without a change. Part 2 shows how.
Between them, these six cover everything the guide needs: a product with three owners, foundations that other modules plug into, pages that combine several modules, and a checkout that runs through Orders, Inventory, Payment and Shipping and has to survive any of them failing halfway.
These boundaries aren’t perfect. We’ll discover friction as we build, and that’s normal: a boundary is a guess made at the moment you know the least about the domain.
So guess coarse. If you’re unsure whether something is one module or two, make it one. Splitting a big module later is cheap: the code that moves out already lives together, and the compiler tells you every place that has to change. Merging two modules back together is the expensive direction. By then each has its own API, its own schema and its own events, and everything that grew up around the seam has to be undone. Enforced boundaries (next part) make a wrong boundary visible early, but they don’t make it free to move.
Part 2: Enforcing the Lines
Boundaries on a whiteboard are aspirations. Boundaries in the build system are architecture. This part makes an invalid dependency a failing build, not a code review discussion.
Contracts, Not Implementations
When Orders needs a price, the obvious approach is to call the Products service directly:
class OrderPricing(
    private val productService: ProductService,  // the implementation, from Products
) {
    fun priceOf(productId: ProductId, quantity: Int): Money =
        productService.getProduct(productId).price * quantity
}
This works, but it creates tight coupling. Orders now depends on ProductService, a concrete class with its own dependencies, internal structure, and implementation details. And the coupling is transitive: ProductService depends on ProductRepository, which depends on database entities. Orders has indirectly coupled itself to the Products database schema.
The fix is depending on a contract instead of an implementation:
interface ProductApi {
    fun getProduct(id: ProductId): ProductDto
}

class ProductService(
    private val repository: ProductRepository,
) : ProductApi {
    override fun getProduct(id: ProductId): ProductDto { ... }
}

class OrderPricing(
    private val products: ProductApi,  // the contract, not the implementation
) {
    fun priceOf(productId: ProductId, quantity: Int): Money =
        products.getProduct(productId).price * quantity
}
Now Orders depends on ProductApi, an interface with no implementation details. The Products team can refactor their internals, change their tables, swap out libraries. As long as they fulfill the contract, Orders won’t notice. (What happens when the product doesn’t exist is a question for Part 7.)
But where does the contract live? If the interface sits right next to its implementation, nothing stops Orders from reaching past it. There are two ways to draw that line, and they make a good first and second step.
Step One: Packages and a Test
Spring Modulith treats each top-level package as a module. Classes directly in a module’s package are its API; anything in subpackages is internal:
com.example.shop/
├── products/
│   ├── ProductApi.kt            # API: other modules may use it
│   ├── ProductDto.kt
│   └── internal/                # internal: hidden
│       ├── ProductService.kt
│       └── ProductRepository.kt
└── orders/
    └── ...
A test verifies the structure, and fails if any module uses another one’s internals or if modules depend on each other in a cycle:
@Test
fun `verify module structure`() {
    ApplicationModules.of(Application::class.java).verify()
}
You can be more precise than “top-level package = module”. @ApplicationModule(allowedDependencies = ["products", "inventory", "payment", "users"]) on a module’s package-info.java restricts which modules it may use at all, and @NamedInterface publishes a specific subpackage (say products.spi) as part of the API without opening up the rest.
That’s the left side of the dial: the dependency graph, checked from day one, for the cost of one test. Spring Modulith brings more that we’ll use later: listeners that behave across transactions and an event outbox (Part 5), tests that start one module at a time (Part 9), and diagrams of your modules generated from the code.
Step Two: Separate Gradle Modules
The test catches a violation in CI. The compiler catches it before you’ve finished typing. To get there, split each module into two Gradle modules:
products/
├── products-api/     # The contract
└── products-impl/    # The implementation
The rules are simple. An -impl module depends on its own -api (it implements the contract). Other modules depend only on -api modules, never on -impl. No circular dependencies.
// orders-impl/build.gradle.kts
dependencies {
    implementation(project(":orders:orders-api"))
    implementation(project(":products:products-api"))  // contract only
    implementation(project(":inventory:inventory-api"))
    implementation(project(":payment:payment-api"))
    implementation(project(":users:users-api"))
    // products-impl isn't on the list, and can't be: that's the whole point
}
If someone tries to import a class from products-impl, the build fails. No discussion needed.
There’s a bonus: faster builds. Gradle only recompiles a module’s dependents when its public signatures (its ABI) change. Since everyone depends on -api modules, which change rarely, a change inside products-impl recompiles products-impl and nothing else. In a single-module monolith, every change can recompile everything.
Make the move when the test stops being enough: when several teams work in the codebase, when agents write much of the code (Part 12), or when you want those build times. This guide uses the Gradle setup from here on, together with Spring Modulith for its events, tests and documentation. If you stay with packages, read products-api as “the top-level products package” and products-impl as “everything in products.internal”. Everything else carries over.
ProductApiProductDto,ProductIdProductError- events, like
ProductRenamedEvent spi/: questions it asks others- test fixtures: a fake and builders
internal- the domain:
Productand its rules ProductService- controllers, repositories, listeners
- migrations for its schema
productsits data, and nobody else's- tables only Products touches
- its own database role
- no foreign keys out
What Goes in the Contract
The -api module holds what other modules use: interfaces defining what the module can do, DTOs for data exchange, value types like IDs, events other modules might listen to, and error types so callers know what can go wrong.
// products-api
@JvmInline
value class ProductId(val value: String) {
    init {
        require(value.isNotBlank()) { "ProductId cannot be blank" }
    }
}

enum class ProductStatus { DRAFT, ACTIVE, DISCONTINUED }

data class ProductDto(
    val id: ProductId,
    val name: String,
    val price: Money,
    val status: ProductStatus,
)

sealed interface ProductError {
    data class NotFound(val id: ProductId) : ProductError
    data object DeletionBlocked : ProductError
}

interface ProductApi {
    fun getProduct(id: ProductId): Result<ProductDto, ProductError>
    fun getProducts(ids: Set<ProductId>): List<ProductDto>
    fun deleteProduct(id: ProductId): Result<Unit, ProductError>
}
Value types with simple validation belong here. Other modules benefit from knowing they’re working with a valid ProductId, not just a String.
What stays internal is behavior. Business rules, state transitions, invariants: the logic that makes your domain more than a data container. Mark it internal so Kotlin reinforces the boundary:
// products-impl
internal data class Product(
    val id: ProductId,
    val name: String,
    val price: Money,
    val status: ProductStatus,
) {
    fun discontinue(): Product {
        check(status != ProductStatus.DISCONTINUED) { "Already discontinued" }
        return copy(status = ProductStatus.DISCONTINUED)
    }
}

internal fun Product.toDto() = ProductDto(id = id, name = name, price = price, status = status)
The rule of thumb: if it’s just data and validation, it can be public. If it’s behavior, keep it internal.
And keep the contract shaped by its callers. Contracts grow one “while we’re at it” at a time, and a ProductDto that carries every field any caller ever wanted is the God object from Part 1, back through the API. Notice what ProductDto doesn’t have: a weight. Shipping owns that. Before adding a field or a method, ask who calls it and what they actually need. Don’t publish types “just in case”: if no other module needs it, it stays in -impl. And if one interface ends up serving very different callers, say a checkout reading prices and a back office editing products, it’s fine to split it in two.
Foreign References
There’s a subtle trap when defining contracts. Payment needs to know what it’s taking money for, and the natural answer is an order:
// payment-api
interface PaymentApi {
    fun startPayment(orderId: OrderId, amount: Money): Result<PaymentDto, PaymentError>  // OrderId?
}
OrderId lives in orders-api, so payment-api now depends on orders-api. But Orders already depends on Payment, to start payments. Two modules that depend on each other are a cycle, and Gradle won’t compile it. Even where a cycle is allowed, Payment has just become a module about orders.
The instinct is to extract the ID types to a common module. That works initially. Then Inventory needs ProductId. Then Shipping needs OrderId. Soon your common module contains every ID type in the system, and you’ve recreated coupling with extra steps.
The fix: each module only defines types it owns. For a reference to something it doesn’t own, it can use a primitive or, to keep an order’s ID from being passed where a payment’s goes, a reference type of its own:
// payment-api
@JvmInline value class PaymentReference(val value: String)  // whatever the caller wants back

interface PaymentApi {
    fun startPayment(reference: PaymentReference, amount: Money): Result<PaymentDto, PaymentError>
    fun refund(paymentId: PaymentId): Result<Unit, PaymentError>
}

data class PaymentCompletedEvent(
    val paymentId: PaymentId,
    val reference: PaymentReference,
    val amount: Money,
    val completedAt: Instant,
)
Type safety without coupling. The caller converts at the boundary, in both directions:
// orders-impl
payments.startPayment(PaymentReference(order.id.value), order.total)

// ...and when the payment comes back (more on listeners in Part 5)
val orderId = OrderId(event.reference.value)
You need this for references that point up, against the direction of the dependencies. When a dependency only flows one way, be pragmatic. Shipping always works for an order, and Orders never needs a shipment ID in its contract, so shipping-api can depend on orders-api and use OrderId directly.
Keeping Bounded Contexts Clean
Look at the dependency graph from Part 1 again. It’s layered: foundational modules at the bottom know nothing about the modules above them. Products defines what you can buy; it shouldn’t need to know that orders exist. A product exists whether anyone ordered it or not.
That isn’t only a technical constraint. Every dependency accumulates knowledge. When Products depends on Orders, the Products team needs to understand order concepts to work on their module.
When an arrow would point upward, pause and reconsider. Usually there’s an event that could flow the other direction, or an SPI waiting to be extracted (next section).
Events don’t make a dependency disappear, though. They flip who knows whom: the listener depends on the publisher’s -api, because that’s where the event class lives. When a parcel is delivered, Orders wants to know:
// orders-impl
@Component
internal class DeliveryListener(
    private val orders: OrderService,
) {
    @ApplicationModuleListener  // more on listeners in Part 5
    fun on(event: ShipmentDeliveredEvent) {
        orders.markDelivered(event.orderId, event.deliveredAt)
    }
}
So orders-impl depends on shipping-api: the dashed arrow in the diagram, pointing upward after all. That’s a deliberate trade. It’s the weakest kind of dependency (Orders knows one event class, nothing about how Shipping works), it lives in -impl only, and the alternative, Shipping calling orders.markDelivered(), would make Shipping drive the order’s lifecycle. Upward arrows like this one should be rare, deliberate, and visible in your validation rules, not something that just happens.
Service Provider Interfaces
Sometimes a foundational module needs input from higher-level modules without depending on them. Products wants to prevent deletion of a product with open orders, but shouldn’t know about Orders.
The solution is a Service Provider Interface (SPI). Products defines an interface for the question it wants to ask. Other modules provide answers by implementing it.
// products-api/spi/ProductDeletionBlocker.kt
interface ProductDeletionBlocker {
    fun canDelete(productId: ProductId): Boolean
}
Orders implements it:
// orders-impl
@Component
internal class OpenOrdersBlockDeletion(
    private val orders: OrderRepository,
) : ProductDeletionBlocker {
    override fun canDelete(productId: ProductId): Boolean =
        !orders.existsOpenForProduct(productId)
}
Products consumes all implementations without knowing where they come from:
// products-impl
@Service
internal class ProductService(
    private val repository: ProductRepository,
    private val deletionBlockers: List<ProductDeletionBlocker>,
) : ProductApi {

    override fun deleteProduct(id: ProductId): Result<Unit, ProductError> {
        if (deletionBlockers.any { !it.canDelete(id) }) {
            return Err(ProductError.DeletionBlocked)
        }
        repository.delete(id)
        return Ok(Unit)
    }
}
Spring collects all beans implementing ProductDeletionBlocker and injects them as a list. Products doesn’t know who’s blocking or why; it just asks. The knowledge stays where it belongs.
Source Sets Count Too
Test code can cross a boundary just as easily as main code. Orders’ tests need a product, and there’s a perfectly good builder in the test fixtures of products-impl. Use it, and Orders’ tests are coupled to Products’ internals.
So test fixtures follow the same rules as main code: a module’s tests may use the test fixtures of another module’s -api, never of its -impl. That’s where Products shares what other modules’ tests need: a fake and a few builders (Part 9).
Automated Enforcement
Gradle modules prevent most violations: you can’t import what you can’t depend on. But some rules need explicit checks, like ensuring no -api module depends on an -impl module, that test fixtures respect boundaries, or that upward arrows stay on an agreed list.
Write a validation task that fails the build on violations, and run it as part of CI. The example code has one as a Gradle plugin: module validation. If you’d rather write such rules as tests, ArchUnit (Java) and Konsist (Kotlin) do the same job for rules inside a module, like “nothing in domain imports Spring”.
Rules about who owns what are worth enforcing too. A CODEOWNERS file that maps each module directory to a team means a change to products-api automatically asks the Products team for a review. The contract can’t change without its owners noticing.
Architecture enforced by the build system survives deadlines, new team members, and “temporary” workarounds. Architecture enforced by documentation survives until the first Thursday afternoon crunch.
Part 3: Inside the Modules
With the boundaries enforced, the hard part is done. What happens inside each -impl module matters much less: a mess in one module can’t leak into others, and you can reorganize it later without coordinating with anyone. One principle is still worth following: dependencies point inward.
The Three Layers
Organize code so that outer layers depend on inner layers, never the reverse.
Domain is the core: business logic, entities, value objects, repository interfaces. No framework dependencies, just plain Kotlin. The domain defines what the system does, not how it connects to the outside world.
Application orchestrates: it implements the API contract, coordinates domain operations, handles transactions, publishes events. Application code uses domain types and repository interfaces but doesn’t know about databases or HTTP.
Infrastructure connects to the outside world: controllers, repository implementations, event listeners, external API clients. This is where Spring annotations live, where SQL gets written, where HTTP requests get parsed.
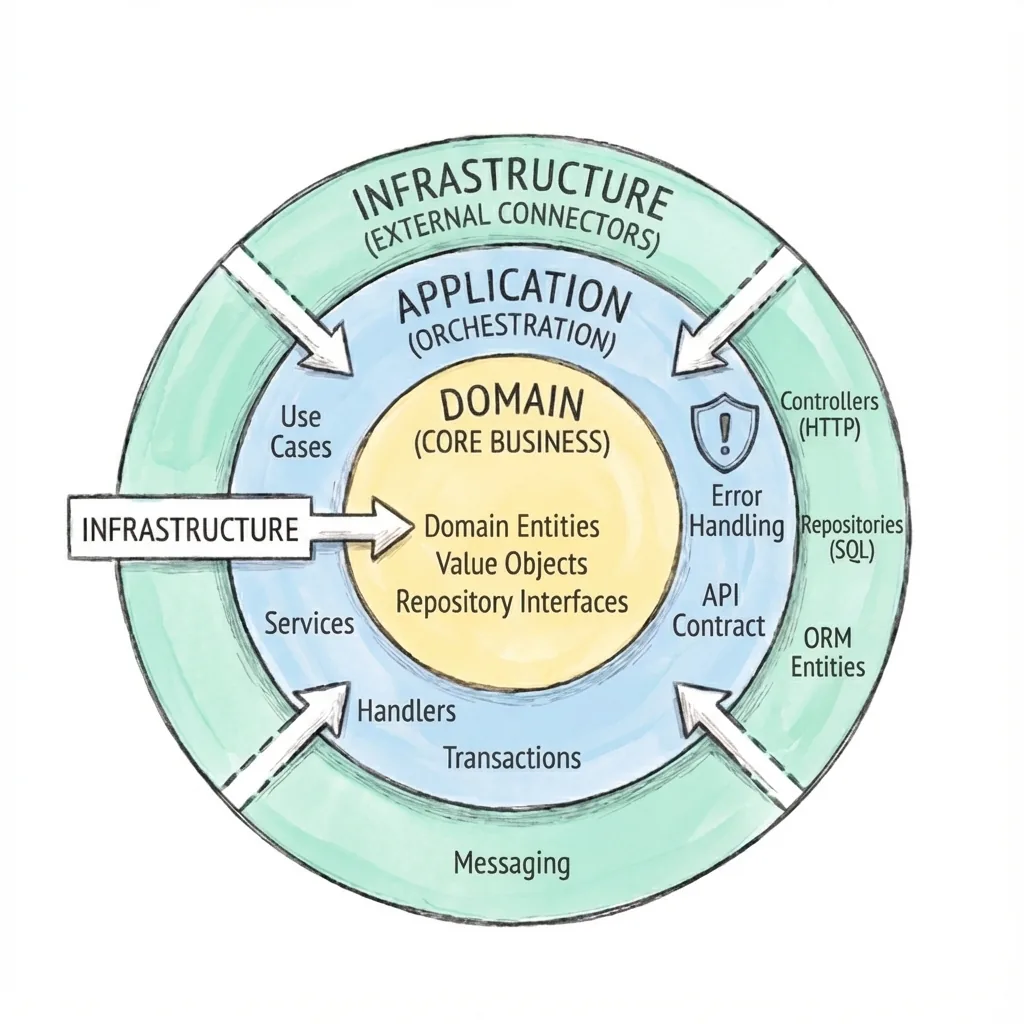
The dependency direction: infrastructure → application → domain. A request flows inward: the controller (infrastructure) calls a handler (application), which uses domain types and a repository interface. The repository implementation (infrastructure) knows how to persist those types, but the domain doesn’t know the implementation exists.
This keeps your business logic testable without frameworks, and keeps infrastructure changes contained. Swapping your HTTP client, your message broker or your persistence library touches infrastructure, not the business rules. (Don’t oversell this to yourself: moving from Postgres to MongoDB changes your transaction and query model too, and that will reach past the repository. But it reaches a lot less far.)
Organizing Inside the Module
When a module grows several features, vertical slices work well. Each feature gets a subpackage with its own logic, persistence and REST concerns. Shared concepts stay in the module root.
products-impl/
└── src/main/kotlin/com/example/shop/products/
    ├── Product.kt                    # shared domain
    ├── ProductRepository.kt          # shared persistence
    ├── ProductFacade.kt              # implements ProductApi
    ├── import/
    │   ├── ImportHandler.kt
    │   ├── ImportJob.kt
    │   ├── persistence/
    │   └── rest/
    └── pricing/
        ├── PricingHandler.kt
        ├── PriceCalculator.kt
        ├── persistence/
        └── rest/
When you need to understand pricing, you open one folder. Other modules still see one interface: ProductFacade implements ProductApi and only delegates to the handlers.
But don’t overthink this. Pick something reasonable and move on. You can always reorganize later.
When to Skip All This
Layers and use-case slicing add value when you have complex domain logic that benefits from isolation, multiple entry points (REST, events, scheduled jobs) to the same operations, or a need to swap infrastructure components.
They add overhead when you’re building straightforward CRUD, when the module is small and unlikely to grow, or when you’re prototyping and don’t know what the domain looks like yet.
Start simple. Add structure when the code tells you it needs it: when you’re afraid to touch a class because it does too many things, or when testing requires mocking half the framework. Structure is a response to pain, not a prerequisite.
Part 4: Isolating Data
You can have perfectly separated modules, clean APIs and enforced dependencies, and still end up with a tightly coupled system, because of the database. A shared table, or a foreign key across modules, is a dependency no Gradle configuration can catch.
The Shared Database Trap
It usually starts innocently. Inventory’s stock screen lists products by name, twenty to a page. Products already has a product table with the names in it. Why not just join?
-- In Inventory's code
SELECT s.product_id, s.on_hand, p.name
FROM stock s
JOIN product p ON p.id = s.product_id
ORDER BY p.name
LIMIT 20 OFFSET 40
This works. It’s fast. It’s “just one query.”
It’s also invisible coupling. Now Inventory depends on the Products table structure. If Products renames name to title, Inventory breaks. If Products moves to a different database, Inventory breaks. And nobody sees this dependency in the code; it lurks in SQL strings, waiting to cause an incident during an otherwise routine deployment.
Schema Per Module
The fix is giving each module its own database schema. Products owns the products schema. Inventory owns the inventory schema. A module only touches tables in its own schema.
CREATE SCHEMA products;
CREATE SCHEMA inventory;

CREATE TABLE products.product (
    id VARCHAR(64) PRIMARY KEY,
    name VARCHAR(200) NOT NULL,
    price_amount NUMERIC(12, 2) NOT NULL,
    price_currency CHAR(3) NOT NULL
);

CREATE TABLE inventory.stock (
    product_id VARCHAR(64) PRIMARY KEY,  -- just data, no FK
    on_hand INT NOT NULL,
    reserved INT NOT NULL
);
Each module gets its own Flyway configuration pointing at its schema. Migrations live with the module code. When there’s a problem with the stock table, there’s no ambiguity about who owns it. You can check the example implementation here.
So far, though, this is still convention. One application usually means one connection pool and one database user, and that user can read every schema. Nothing stops a JOIN products.product from sneaking into Inventory’s SQL.
To make it a rule, let the database enforce it. Give each module its own role that can only touch its own schema:
CREATE ROLE inventory_module LOGIN PASSWORD '...';
GRANT USAGE ON SCHEMA inventory TO inventory_module;
GRANT SELECT, INSERT, UPDATE, DELETE ON ALL TABLES IN SCHEMA inventory TO inventory_module;
ALTER DEFAULT PRIVILEGES IN SCHEMA inventory
    GRANT SELECT, INSERT, UPDATE, DELETE ON TABLES TO inventory_module;
-- no grants on products, orders, ...: a cross-schema query is now "permission denied"
You then have two options. The strict one is a data source per module, each connecting with its own role. That’s the real thing, but it means several connection pools, and a transaction can no longer span two modules, which, as Part 5 argues, is something you want to get rid of anyway. The cheap one is to keep a single data source in production, but run each module’s tests (Part 9) connected as that module’s role. A stray cross-schema join then fails in CI, long before it can cause an incident. Start with the cheap one; it catches nearly everything.
No Foreign Keys Across Schemas
This is the rule that makes people uncomfortable: no foreign keys between schemas.
-- Don't do this
CREATE TABLE inventory.stock (
    product_id VARCHAR(64) PRIMARY KEY REFERENCES products.product(id),  -- No!
    ...
);

-- Do this instead
CREATE TABLE inventory.stock (
    product_id VARCHAR(64) PRIMARY KEY,  -- just a value
    ...
);
Referential integrity across module boundaries becomes your responsibility at the application level. When Inventory receives stock, it checks that the product exists by asking Products:
override fun receiveStock(productId: ProductId, units: Int): Result<StockDto, InventoryError> {
    products.getProduct(productId)
        .getOrElse { return Err(InventoryError.UnknownProduct(productId)) }

    val stock = repository.findByProductId(productId) ?: Stock.empty(productId)
    return Ok(repository.save(stock.receive(units)).toDto())
}
Yes, this is more work than a foreign key. But it’s explicit: visible in the code, testable, and under your control. And when you eventually need to extract a module into its own service, there are no cross-schema constraints to untangle.
What About Joins?
The most common concern: “I used to join these in one query. Now what?” It depends on the query.
For lookups and short lists, batch. Collect the IDs, fetch them in one call, then join in memory. Say a customer’s recent orders are shown with a current picture of each product:
fun recentOrders(customer: UserId): List<OrderSummary> {
    val orders = orderApi.recentOrders(customer)
    val productIds = orders.flatMap { it.lines }.map { it.productId }.toSet()
    val products = productApi.getProducts(productIds).associateBy { it.id }

    return orders.map { order -> OrderSummary(order, products) }
}
(Which module this code lives in is a question for Part 8.)
For sorting and paging by another module’s data, keep a read model. Batching works as long as one module decides which rows you get. It breaks when another module’s data decides which rows or in what order, like the stock screen above: sorted by product name, page 3. You’d have to load every stock row before you know which twenty land on page 3.
So the module that owns the screen keeps its own copy of the foreign data it needs, shaped for the query, and keeps it up to date by listening to events (plus a one-off backfill through the Products API when you first add it):
// inventory-impl
@Component
internal class ProductNames(
    private val names: ProductNameRepository,  // table inventory.product_name
) {
    @ApplicationModuleListener
    fun on(event: ProductRenamedEvent) {
        names.upsertIfNewer(event.productId, event.newName, event.version)
    }
}
Now Inventory joins inventory.stock with inventory.product_name in its own schema, with paging and sorting in SQL, without touching Products’ tables.
Two things to know. The copy is eventually consistent: for a moment after a rename, the stock screen shows the old name. For a list screen, that’s almost always fine; if it isn’t, that’s a sign the two things belong in the same module. And listeners run asynchronously (Part 5), so two quick renames can arrive in either order. That’s what the version is for: Products increments it on every change, and the copy only accepts a newer one (... ON CONFLICT (product_id) DO UPDATE ... WHERE product_name.version < excluded.version).
For history, copy at write time. An order should show the product name and price at the time of purchase, not whatever the product is called today. Copy the relevant fields when creating the order. The data belongs to the order now; it’s capturing a moment in time.
For analytics and reporting, be pragmatic. A read-only reporting schema with cross-module views is fine for dashboards. Just keep it separate from your application code.
Changing a Schema While It Runs
One deployable doesn’t mean one moment of deployment. During a rolling deploy, old and new versions of your code run side by side against the same schema.
So change a schema in two steps, a pattern called expand and contract. First expand: add the new column or table, with a default, and deploy code that writes both and reads the new. Then, once nothing reads the old one, contract: remove it, in a later deploy. Never rename a column in one step. Each module’s migrations are its own business, but every module plays by this rule.
Part 5: Module Communication
Modules need to talk to each other: an order needs a price, and Shipping needs to know when an order is confirmed. Two patterns cover most cases: synchronous calls when you need an answer now, and events when you’re announcing that something happened.
Synchronous Calls
The simplest pattern: one module calls another’s API and waits for the response.
// orders-impl
@Component
internal class OrderPricing(
    private val products: ProductApi,
) {
    fun priceLine(request: OrderLineRequest): Result<OrderLine, OrderError> {
        val product = products.getProduct(request.productId)
            .getOrElse { return Err(OrderError.UnknownProduct(request.productId)) }
        if (product.status != ProductStatus.ACTIVE) return Err(OrderError.NotForSale(product.id))

        return Ok(OrderLine(product.id, product.name, product.price, request.quantity))
    }
}
This is appropriate when you need data to proceed and the operation should fail if the dependency fails. The tradeoff is runtime coupling: if Products is slow, ordering is slow. For many operations, that’s exactly right.
Look at the last line. Orders turns Products’ DTO into a type of its own, keeping only what it needs, and copying the name and price as they are right now (Part 4). The rest of Orders works with OrderLine, a type it controls, and never sees ProductDto. When translation grows beyond a line or two, give it a class of its own, an adapter, and keep the other module’s types out of your domain.
Two things to watch, because in-process calls feel free.
The first is chains. There’s no network latency, no retries, no circuit breakers to remind you each call has a cost, so it’s easy to let Orders call Inventory, which calls Products, which calls something else, a little deeper every quarter. Under load, one hot endpoint fans out through half the system. If a call graph between modules is more than one or two hops deep, the data probably wants to live closer to where it’s used (a read model, Part 4), or the work wants to be an event.
The second is transactions. If placeOrder is @Transactional and calls inventory.reserve(), the reservation silently joins the order’s transaction. Roll back the order and the reservation rolls back too. It works, it’s convenient, and it’s a dependency that doesn’t appear in any Gradle file: Orders now relies on Inventory’s writes being atomic with its own. If you ever pull Inventory out into its own service, that guarantee is the first thing that breaks. Prefer one module per transaction. When a business operation has to change two modules, let the first one commit and the second react to its event. Part 6 shows how that works for the operation where it matters most: checkout.
Events
Sometimes a module doesn’t need a response. It’s announcing that something happened, and other modules react if they care.
// orders-api
data class OrderConfirmedEvent(
    val orderId: OrderId,
    val lines: List<OrderLineDto>,
    val shippingAddress: AddressDto,
    val confirmedAt: Instant,
)
The publisher doesn’t know who’s listening. Shipping starts packing. A notifications module, if you add one, sends the confirmation email. Each listener is independent.
Spring’s ApplicationEventPublisher is all you need to publish:
// orders-impl
@Service
internal class OrderService(
    private val repository: OrderRepository,
    private val events: ApplicationEventPublisher,
) {
    @Transactional
    fun confirm(order: Order) {
        val confirmed = repository.save(order.confirm())
        events.publishEvent(confirmed.toConfirmedEvent())
    }
}
The obvious way to listen is Spring’s @TransactionalEventListener(phase = AFTER_COMMIT), which only fires once the order has committed. It has two problems that won’t show up in a demo. It isn’t asynchronous: it runs on the publisher’s thread, so confirm waits for Shipping, and if Shipping throws, the error reaches the caller of a confirmation that succeeded. Its writes can vanish: a plain @Transactional method called from it joins the order’s transaction, which has already finished, and its inserts are never committed. No error, just a shipment that doesn’t exist.
Spring Modulith fixes both with one annotation. @ApplicationModuleListener is @TransactionalEventListener + @Async + @Transactional(propagation = REQUIRES_NEW):
// shipping-impl
@Component
internal class OrderListener(
    private val shipments: ShipmentService,
) {
    @ApplicationModuleListener
    fun on(event: OrderConfirmedEvent) {
        shipments.startFulfilment(event)
    }
}
Now the listener runs after the order commits, on its own thread, in its own transaction. A failure in Shipping can’t reach Orders, and Orders doesn’t wait for Shipping. Use this as your default for listeners in other modules. (Enable async execution with @EnableAsync, and give it a sized executor rather than the default.)
The Dual-Write Problem
One problem is left. Consider this sequence:
- The order’s transaction commits.
- The event is handed to a listener on another thread.
- The listener starts fulfilment.
What if the application stops between 1 and 3? A deploy, an out-of-memory kill, a node that disappears. The order is confirmed, but nobody knows. Shipping never starts, and nothing will ever retry it, because the event only existed in memory.
This is the dual-write problem: two things have to happen (save the order, deliver the event), and only one of them is in the transaction.
The solution is making the event part of the transaction, with a transactional outbox: write the event to a table in the same transaction as your business data. If the transaction rolls back, the event rolls back with it. If it commits, the event is safely stored, and something delivers it, eventually.
You rarely need to build this yourself. Spring Modulith’s event publication registry is an outbox. Add spring-modulith-starter-jdbc (or -jpa), and every event headed for an @ApplicationModuleListener is written to an event_publication table in the publisher’s transaction, then marked completed when its listener succeeds. The publishing code stays a plain publishEvent.
It differs from the textbook outbox in two ways worth knowing. It keeps one row per listener, not one per event, so when Shipping succeeds and Notifications fails, only Notifications is retried. And delivery is immediate: the event goes to its listeners in memory right after commit. The table isn’t the delivery route; it’s the safety net.
For the safety net to catch anything, turn on the staleness monitor (spring.modulith.events.staleness.*, off by default). It marks publications that got stuck as failed, and a scheduled job resubmits the failures through the FailedEventPublications bean.
This guarantees at-least-once delivery. A listener that crashes after doing its work but before its row is marked completed runs again. So listeners have to handle duplicates; make them idempotent:
fun startFulfilment(event: OrderConfirmedEvent) {
    if (shipments.existsForOrder(event.orderId)) return  // already started: a redelivery
    // ...
}
Events Are Contracts
An event class in an -api module is as much a public API as an interface, with one extra catch: events get stored. The registry keeps serialized events until they’re delivered, so during a deploy, the new version of your code may have to read events the old version wrote.
Treat them accordingly. Add fields with defaults; don’t rename or remove them. Don’t move event classes to another package without checking how your registry identifies them. When the meaning changes, publish a new event (OrderConfirmedEventV2, or better, a name that says what’s different) next to the old one, and retire the old one once nobody listens.
One catch is easy to miss: the require checks in a class’s init block (Part 7) run again when a stored event is read back. Tighten a check, and events written before the deploy can’t be read anymore. Keep validation on events loose, or leave it out. An event records something that already happened; it isn’t input to check.
When to Use What
Call when you need an answer to proceed, and keep the chains short. Publish an event when others might care that something happened and the publisher shouldn’t wait for them. Store the event whenever losing it would leave the system wrong: a lost order confirmation is a customer who paid and never gets a parcel. Only things you can afford to drop, like refreshing a cache, can stay in memory. When in doubt, store it; the cost is one table.
A checkout needs all three: a call to reserve stock, events for everything that follows, and the outbox so none of them gets lost. Putting them together is what the next part is about.
Part 6: Processes Across Modules
Up to now, every operation has had a home. Pricing a line happens in Orders. Receiving stock happens in Inventory. Each runs in one module and one transaction, and if it fails, the database rolls it back.
Checkout doesn’t fit. It reserves stock in Inventory, takes money in Payment, confirms the order in Orders and sends a parcel from Shipping. Four modules, and Part 5 just told you not to put them in one transaction. So what happens when the customer closes the tab after the stock is reserved? Or when the payment comes in after you’d given up on it? Without a shared transaction, nothing rolls back on its own. You decide what “undo” means, step by step.
Microservices people call this a saga: a sequence of local transactions, each in one module, with a way to undo each step if a later one fails. In a modular monolith, you don’t need a framework for it. Reservations, the order’s own status and one rule for listeners will do.
First, Try Not to Need One
Before you design a process across modules, check whether it should cross them at all. If two steps must always succeed or fail together, and there’s no meaningful state halfway, that’s the signal from Part 1: they might belong in the same module. A process is for steps that really happen apart (stock held now, money a few minutes later), with a state in between that means something to the business.
Reserve, Don’t Check
The naive checkout checks: is it in stock? Yes? Then place the order. Between the check and the order, someone else buys the last one.
Instead, Inventory takes a reservation. It sets the units aside for one order, until a given time, and nobody else can have them. The order then either commits the reservation (the units are sold) or releases it (they’re back on the shelf):
// inventory-api
@JvmInline value class ReservationId(val value: String)  // chosen by the caller

interface InventoryApi {
    fun reserve(id: ReservationId, lines: List<StockLine>, until: Instant): Result<Unit, InventoryError>
    fun commit(id: ReservationId)
    fun release(id: ReservationId)
}
Two small details carry a lot of weight here. The caller chooses the reservation’s ID (Orders uses the order’s), so every call is idempotent: reserving, committing or releasing the same reservation twice changes nothing the second time. And until makes a reservation expire on its own: a job in Inventory releases whatever nobody committed in time. That expiry is the safety net under everything else in this part. Whatever goes wrong, the stock comes back.
The Order Is the Process
Something has to know where each checkout stands. You could build a separate saga object with its own table. But Orders already has exactly that: an order has a status. Let the order’s lifecycle be the process.
Orders owns the process because it’s what the process is about: the customer places an order, not a reservation or a payment. It’s also the module that already depends on all the others, so it can call them without upward arrows. Inventory and Payment don’t know a checkout exists. They keep reservations and take payments for whoever asks.
Walking Through a Checkout
- Place the orderOrders prices the lines, asks Inventory to reserve them for 30 minutes, and saves the order as awaiting payment. Out of stock? The customer hears it right away.OrdersInventory
- PayThe customer pays. Payment publishes PaymentCompletedEvent, carrying the order's reference.Payment
- ConfirmOrders moves the order to confirmed and publishes OrderConfirmedEvent.Orders
- Follow throughA listener in Orders commits the reservation. Shipping starts packing.InventoryShipping
If anything stops halfway, the order's status says where, and the reservation runs out on its own
Placing the order is the only synchronous step, because the customer is waiting for it:
// orders-impl
override fun placeOrder(request: PlaceOrderRequest, customer: UserId): Result<OrderDto, OrderError> {
    val id = OrderId.generate()
    val lines = request.lines.map { line ->
        pricing.priceLine(line).getOrElse { return Err(it) }
    }

    val until = clock.instant() + RESERVATION_TIME
    inventory.reserve(ReservationId(id.value), lines.map { it.toStockLine() }, until)
        .getOrElse { return Err(OrderError.OutOfStock(it.productIds)) }

    return Ok(orders.place(id, customer, lines, request.shippingAddress))  // Orders' own transaction
}
Notice what isn’t here: a @Transactional around the whole method. The reservation commits in Inventory’s transaction, the order in Orders’ own, inside orders.place. If the application dies between the two, there’s a reservation without an order, and half an hour later there isn’t.
Everything after that happens in listeners:
// orders-impl
@Component
internal class CheckoutProcess(
    private val orders: OrderService,
    private val inventory: InventoryApi,
    private val payments: PaymentApi,
) {
    @ApplicationModuleListener
    fun on(event: PaymentCompletedEvent) {
        val order = orders.get(OrderId(event.reference.value))
        when (order.status) {
            AWAITING_PAYMENT -> orders.confirm(order)       // publishes OrderConfirmedEvent
            CANCELLED -> payments.refund(event.paymentId)   // paid after we gave up on it
            CONFIRMED, DELIVERED -> Unit                    // seen this one before
        }
    }

    @ApplicationModuleListener
    fun on(event: OrderConfirmedEvent) = inventory.commit(ReservationId(event.orderId.value))

    @ApplicationModuleListener
    fun on(event: OrderCancelledEvent) = inventory.release(ReservationId(event.orderId.value))
}
Three things make this robust.
Every transition is guarded. A listener looks at the order’s status before it acts. The outbox delivers at least once, so the same PaymentCompletedEvent can arrive twice; the second time, the order is already confirmed and nothing happens. That’s idempotency without a deduplication table. And the when has no else: add a status, and this stops compiling until someone decides what a payment means in it.
Commands are idempotent too. Committing a reservation twice commits it once. Refunding the same payment twice refunds it once. So when the outbox retries a listener that had already done its work, nothing happens twice.
One rule for listeners: change your own module’s state, or call one command on another module, never both. @ApplicationModuleListener runs in a single transaction. A listener that confirmed the order and committed the reservation would put Orders and Inventory back in one transaction, the hidden coupling from Part 5. That’s why confirming and committing are two listeners, linked by OrderConfirmedEvent, and the outbox retries each on its own.
When Things Go Wrong
The customer never pays. A scheduled job in Orders cancels what’s been waiting too long:
// orders-impl
@Scheduled(fixedDelay = 60_000)
fun cancelUnpaidOrders() {
    orders.findAwaitingPaymentSince(clock.instant() - PAYMENT_TIME)
        .forEach { orders.cancel(it, CancelReason.NOT_PAID) }  // publishes OrderCancelledEvent
}
The payment window (20 minutes) is shorter than the reservation (30), so an order that’s paid in time always finds its stock still waiting. Running several instances, each with this job? Fine, as long as cancel checks the status in the same transaction it writes, for instance with a version column for optimistic locking. The second instance finds the order already cancelled and does nothing.
The payment arrives after all. The customer paid at minute 21, after you cancelled. That’s the CANCELLED branch: refund. You could also try to reserve the stock again and keep the order. It’s a business decision as much as a technical one. Decide it explicitly; the exhaustive when makes sure nobody forgets.
The application crashes halfway. The outbox redelivers what wasn’t completed, the guards skip what was already done, and the commands don’t mind being called twice. In the very worst case, the reservation expires.
Two principles hold all of this together. Undoing isn’t rolling back. Releasing a reservation or refunding a payment is a new business operation with its own record, not a pretend-it-never-happened. The customer sees the refund on their statement. And what’s hardest to undo goes last. A reservation is easy to release, so it comes first. Money is harder to give back, so it’s taken once the stock is safe. A parcel on a truck is hardest of all, so it waits until both are done.
When the Process Outgrows the Order
This holds up for checkout-sized processes: a few steps, minutes long, one obvious owner. If you find yourself with many long-running processes, with days-long approvals, timers and steps that branch and loop, that’s the point where a workflow engine like Temporal or Camunda starts to pay for itself. It’s the far end of the dial. Most shops never get there.
Part 7: Errors and Validation
Errors are where modular codebases quietly rot. One team throws exceptions, another returns nulls, a third invents custom result types. The controller layer becomes a graveyard of catch blocks trying to translate chaos into HTTP status codes.
Make Errors Explicit
The traditional approach:
fun getProduct(id: ProductId): Product {
    return repository.findById(id)
        ?: throw ProductNotFoundException(id)
}
Nothing in the type signature hints that this might throw. You discover ProductNotFoundException exists when it crashes in production, or if you’re lucky, by reading documentation that probably doesn’t exist.
And “product not found” isn’t exceptional. It’s a normal business case, and the code should make it obvious.
Return errors as values instead. Define them in the -api module as a sealed type:
// products-api
sealed interface ProductError {
    data class NotFound(val id: ProductId) : ProductError
    data class InvalidData(val reason: String) : ProductError
    data object DuplicateName : ProductError
    data object DeletionBlocked : ProductError
}

interface ProductApi {
    fun getProduct(id: ProductId): Result<ProductDto, ProductError>
    fun createProduct(request: CreateProductRequest): Result<ProductDto, ProductError>
}
The implementation returns the error instead of throwing it:
// products-impl
override fun getProduct(id: ProductId): Result<ProductDto, ProductError> {
    val product = repository.findById(id) ?: return Err(ProductError.NotFound(id))
    return Ok(product.toDto())
}
Now the type signature tells you everything, and callers handle both cases without a try-catch. Because ProductError is sealed, the compiler knows every possible case: a when over it has to cover them all. Add a new error and every exhaustive when stops compiling until someone decides what it means there. (That only works if you leave out the else branch. An else quietly swallows the cases nobody has thought about yet.) So adding an error is a change to the contract, just like adding a method, and that’s as it should be.
A note on Result types: Kotlin’s built-in
Result<T>won’t do here. It has a single type parameter, and its failure is always aThrowable, so it can’t carry aProductError. The examples use kotlin-result, whoseResult<V, E>is eitherOk(value)orErr(error). Arrow’sEitherdoes the same, with a lot more around it. Whichever you choose, choose one for the whole codebase.
Validation in Init Blocks
Where should validation live? The traditional answer in Spring is JSR-303 annotations: @NotBlank, @Positive, @Valid. It works, but scatters validation rules across annotations that are easy to miss and harder to test than plain code.
A better approach: validate at construction time. If an object exists, it’s valid. Your init blocks act as a firewall, keeping garbage out of your implementation. It’s the spirit of “Parse, don’t validate”: instead of checking a String everywhere it’s used, check it once while turning it into a type that can’t be invalid.
Kotlin gives you require for checking input (it throws IllegalArgumentException: the caller’s fault) and check for checking state (it throws IllegalStateException: something is wrong on our side).
Structural vs. Business Validation
Not all validation belongs in the same place:
| Type | Definition | Location |
|---|---|---|
| Structural | Checks data against itself. No external context needed. (e.g., “Quantity > 0”, “Name not blank”) | API module (init block) |
| Business | Checks data against state or rules. Needs the database or config. (e.g., “Email is unique”, “Product in stock”) | Implementation module (service) |
Structural validation in API modules works well: bad input fails as soon as the request is deserialized, the code documents the requirements for callers, and your domain logic doesn’t need defensive checks everywhere.
// orders-api
data class PlaceOrderRequest(
    val lines: List<OrderLineRequest>,
    val shippingAddress: AddressDto,
    // no customer ID: who's ordering comes from the login, not the request (Part 8)
) {
    init {
        require(lines.isNotEmpty()) { "Order must contain at least one item" }
    }
}

data class OrderLineRequest(
    val productId: ProductId,
    val quantity: Int,
) {
    init {
        require(quantity > 0) { "Quantity must be positive" }
    }
}
One limitation: an init block stops at the first failure. For an API called by other code, that’s fine. For a form where a person wants to see every invalid field at once, annotation-based validation, which collects them all, gives the better experience. You can mix the two.
Keep volatile rules out of the API. require(name.isNotBlank()) is fine. A maximum length or a password policy can change, and the contract shouldn’t have to change with it. Rules like that, and every rule that needs the database, go in the service, which returns them as errors:
// products-impl
override fun createProduct(request: CreateProductRequest): Result<ProductDto, ProductError> {
    if (request.name.length > MAX_NAME_LENGTH) {
        return Err(ProductError.InvalidData("Name can be at most $MAX_NAME_LENGTH characters"))
    }
    if (repository.existsByName(request.name)) return Err(ProductError.DuplicateName)
    // ...
}
That’s the whole split: the request checks its own shape, the service checks the rules, and the user gets an error that explains itself. check is for something else: state your own code got wrong, like discontinuing a product that’s already discontinued (Part 2). If one of those fails, it’s a bug, and a 500 is the honest answer.
Translating Errors to HTTP
The domain doesn’t know about HTTP. It returns ProductError.NotFound. Somewhere, that needs to become a 404.
That translation happens at the controller:
@RestController
internal class ProductController(
    private val products: ProductApi,
) {
    @GetMapping("/products/{id}")
    fun getProduct(@PathVariable id: ProductId): ProductDto =
        products.getProduct(id).getOrElse { throw it.toResponseStatusException() }
}

private fun ProductError.toResponseStatusException() = when (this) {
    is ProductError.NotFound -> ResponseStatusException(NOT_FOUND, "Product not found: ${id.value}")
    is ProductError.InvalidData -> ResponseStatusException(BAD_REQUEST, reason)
    ProductError.DuplicateName -> ResponseStatusException(CONFLICT, "Product name already exists")
    ProductError.DeletionBlocked -> ResponseStatusException(CONFLICT, "Product is still in use")
}
With spring.mvc.problemdetails.enabled=true, Spring Boot renders ResponseStatusException as a Problem Details response (RFC 9457, the successor to RFC 7807). The domain stays clean. The HTTP translation is explicit and in one place. And because the when has no else, a new error type won’t compile until you’ve decided which status it maps to.
That leaves the require checks in request classes. When one fails while a request body is read, Spring wraps it in an HttpMessageNotReadableException, and a small @RestControllerAdvice turns that into a 400.
Don’t go further and turn every IllegalArgumentException into a 400. A require that fails while reading a request is the client’s fault. One that fails anywhere else, deep in your code or in a library, is yours, and it should reach Spring’s default handling as a logged 500, not be sent back to the client as if they’d made a mistake.
When Exceptions Are Still Fine
Exceptions still have their place: a lost database connection, a full disk, a bug. The distinction: if the caller can reasonably do something about it, return a Result. If it’s an unexpected failure that should abort the operation, throw.
Part 8: Facing the Outside World
So far, modules have talked to each other. But a shop has customers, and customers don’t call ProductApi. They click around a website. Between their browser and our modules, three questions need answers: what does the outside world get to see, where does a page that needs several modules get built, and who’s asking?
Two Kinds of API
Every module now has two kinds of contract. The -api module is for the rest of the codebase: every caller is in the same repository, the compiler checks each one, and you can change a method and all its callers in one commit. The HTTP endpoints are for callers you don’t compile: a browser running last week’s JavaScript, a mobile app that updates when its users feel like it, a partner’s integration.
Controllers live in the module that owns the resource: /products in products-impl, /orders in orders-impl. They’re infrastructure (Part 3), they translate errors to status codes (Part 7), and they only call their own module.
What they return depends on who’s calling. For your own web frontend, deployed together with the backend, returning the -api DTOs is fine: it’s one less mapping, and a change shows up on both sides at once. For clients you don’t deploy yourself, give the public API models of its own, and version them (/v1/...). Then reshaping a DTO stays an internal change, and breaking a partner is something you decide on purpose.
Pages That Need Several Modules
Remember the product page from Part 1: name and price from Products, “in stock” from Inventory, a delivery estimate from Shipping. None of them owns the page. Putting it in Products would make Products depend on Inventory and Shipping, upward. Putting it in the frontend means three requests and three error cases in JavaScript.
Give it a module of its own: a thin storefront that depends only on -api modules. It has no tables and no business rules. It asks, and it assembles:
// storefront
@RestController
internal class ProductPageController(
    private val products: ProductApi,
    private val inventory: InventoryApi,
    private val shipping: ShippingApi,
) {
    @GetMapping("/shop/products/{id}")
    fun page(@PathVariable id: ProductId): ProductPage {
        val product = products.getProduct(id).getOrElse { throw it.toResponseStatusException() }
        return ProductPage(
            product = product,
            available = inventory.available(id),
            delivery = shipping.estimateDelivery(id),
        )
    }
}
For the frontend it’s one endpoint. For the architecture, it’s a leaf at the top of the graph that nobody depends on. Mauro Servienti calls this view model composition. The recent orders from Part 4, with their batched product lookup, live here too.
Keep it thin. The moment the storefront starts deciding things (“show free delivery if the parcel is light and the customer is a member”), that’s a rule, and rules belong to the module that owns the data behind them. Ask Shipping whether delivery is free, and let the storefront just show the answer.
Who’s Asking?
Authentication happens once, at the edge. Spring Security lives in the application module (Part 10): it checks the session or token on every request and turns it into a user. The modules never see a token, a cookie or a SecurityContext.
What they see is a plain value: the UserId from users-api. Users is a foundation, so every module may depend on it, and a user ID means the same thing everywhere. The controller passes it into the API explicitly:
// orders-impl
@GetMapping("/orders/{id}")
fun getOrder(@PathVariable id: OrderId, @AuthenticationPrincipal jwt: Jwt): OrderDto =
    orders.getOrder(id, requestedBy = UserId(jwt.subject))
        .getOrElse { throw it.toResponseStatusException() }

override fun getOrder(id: OrderId, requestedBy: UserId): Result<OrderDto, OrderError> {
    val order = repository.findById(id)
    if (order == null || order.customerId != requestedBy) return Err(OrderError.NotFound(id))
    return Ok(order.toDto())
}
There are two kinds of authorization, and they live in two places. Rules about roles, like “only support staff may use this endpoint”, are about the request: put them at the edge, with @PreAuthorize on the controller. Rules about data, like “a customer sees only their own orders”, are business rules: they belong in the module that owns the data. Orders knows who placed an order; nobody else should have to. And note the NotFound: as far as this customer is concerned, someone else’s order doesn’t exist. A 403 would confirm that it does.
Passing the user explicitly, rather than reading it from wherever Spring keeps it, pays off as soon as you hit events. An @ApplicationModuleListener runs on another thread, after the request is done, with no security context at all. If a listener needs to know who did something, the event says so: OrderCancelledEvent(orderId, reason, cancelledBy: UserId?), with null when the system did it. The listeners themselves act as the system: they carry out something that’s already been decided, so they don’t ask for permission.
Part 9: Testing
Module boundaries make natural test boundaries. Each module has a clear API and explicit dependencies, which suggests a strategy: test one module completely, and stand in for the others.
Module Tests
Orders depends on ProductApi and InventoryApi, not on their implementations. In tests, provide stand-ins for Products and Inventory and test Orders in isolation: real database, real transactions, real queries, without Products or Inventory existing at all. Connect as the module’s own database role (Part 4), and a stray query into another module’s schema fails right here.
Gherkin works well for expressing what a module should do:
Feature: Checkout

  Scenario: An order waits for its payment
    Given a product "p-42" priced at €29.99
    And 3 units of "p-42" in stock
    When I order 1 "p-42"
    Then the order is awaiting payment
    And 1 unit of "p-42" is reserved for it

  Scenario: Out of stock
    Given a product "p-42" priced at €29.99
    And 0 units of "p-42" in stock
    When I order 1 "p-42"
    Then the order fails with "OutOfStock"
The step definitions don’t create real products or real stock. They put them into fake Products and Inventory modules:
@Given("a product {string} priced at €{bigdecimal}")
fun product(id: String, price: BigDecimal) {
    products.add(buildProductDto(id = ProductId(id), price = Money(price, EUR)))
}
When a module test fails, you know which module broke. When it passes, you have confidence the module actually fulfills its contract against a real database. These are often your highest-value tests: fast enough to run frequently, realistic enough to catch real bugs.
Fakes and Contract Tests
Where does FakeProductApi come from? The Products team ships it, in the test fixtures of products-api:
// products-api testFixtures
class FakeProductApi : ProductApi {
    private val products = mutableMapOf<ProductId, ProductDto>()

    fun add(product: ProductDto) {
        products[product.id] = product
    }

    override fun getProduct(id: ProductId): Result<ProductDto, ProductError> =
        products[id]?.let(::Ok) ?: Err(ProductError.NotFound(id))

    // ... the rest of the interface
}
You could stub ProductApi with a mocking library in every test instead. It works, but each test then encodes its own guess about how Products behaves. Does an unknown ID give NotFound, or an empty result, or an exception? Twenty test files, twenty guesses, and nothing tells you when one of them stops being true. A shared fake is one guess, owned by the team that knows the answer.
And that guess can be checked. Write the expected behavior once, as an abstract test, and run it against both the fake and the real thing:
// products-api testFixtures
abstract class ProductApiContract {
    abstract val products: ProductApi
    abstract fun givenProduct(product: ProductDto)

    @Test
    fun `returns a product that exists`() {
        val product = buildProductDto()
        givenProduct(product)

        assertThat(products.getProduct(product.id).get()).isEqualTo(product)
    }

    @Test
    fun `returns NotFound for an unknown id`() {
        val id = ProductId("unknown")

        assertThat(products.getProduct(id).getError()).isEqualTo(ProductError.NotFound(id))
    }
}
products-api runs it against FakeProductApi; products-impl runs it against ProductService with a real database. If the two ever disagree, a test fails in the Products build, before anyone else’s tests start lying to them. This is the in-process version of consumer-driven contract testing, and it’s the piece that makes “test one module, stand in for the others” trustworthy.
You don’t need one for every module from day one. A fake starts paying for itself when a module gets its second consumer; until then, a fake in the one module that uses it is fine.
Testing What Happens After Commit
Some behavior only shows up after a commit, on another thread: the listeners. Spring Modulith’s Scenario publishes an event and waits for the one you expect:
@ApplicationModuleTest
class CheckoutProcessTests {

    @Test
    fun `a completed payment confirms the order`(scenario: Scenario) {
        val order = givenOrderAwaitingPayment()
        val paid = PaymentCompletedEvent(aPaymentId(), PaymentReference(order.id.value), order.total, now())

        scenario.publish(paid)
            .andWaitForEventOfType(OrderConfirmedEvent::class.java)
            .matching { it.orderId == order.id }
            .toArriveAndVerify { assertThat(it.lines).hasSize(1) }
    }
}
This is where the process from Part 6 gets its tests, one for every arrow in the diagram, and one for each thing that goes wrong. Publish the same event twice and check that the second one changes nothing. Cancel an order, then publish its payment, and check for the refund. These are the tests that prove the guards work.
Unit and Repository Tests
Module tests cover most scenarios, but some things deserve focused tests.
Complex logic that doesn’t need a database (calculations, state machines, validation rules) is faster to test in isolation, as plain unit tests.
Complex queries where the logic lives in SQL also deserve their own tests. Filters, pagination, edge cases with NULL values: these are hard to get right and easy to break. Test them against a real Postgres with Testcontainers. Don’t use H2 “because it’s faster”; it behaves differently in ways that will bite you.
If a method just does findById or delegates to a repository and maps the result, skip the dedicated test: the module test already covers it.
Application-Level Tests
Sometimes you need to verify the full flow: all modules wired together, a real database and real events, from logging in to a parcel being packed. These tests are slow and brittle, and when they fail, the cause isn’t always obvious. Keep them few, for the customer journeys where an integration failure would be costly, and let module tests handle the detailed behavior.
Test Fixtures
Tests need data. You don’t want every test constructing objects from scratch, but you also don’t want shared fixtures that create invisible dependencies between tests.
Builder functions with default arguments hit the sweet spot:
fun buildProductDto(
    id: ProductId = ProductId(UUID.randomUUID().toString()),
    name: String = "Test Product",
    price: Money = Money(BigDecimal("9.99"), EUR),
    status: ProductStatus = ProductStatus.ACTIVE,
) = ProductDto(id = id, name = name, price = price, status = status)

// Only specify what matters for this test
val expensive = buildProductDto(price = Money(BigDecimal("999"), EUR))
When you read a test that says buildProductDto(price = ...), you know the price matters. Everything else is scaffolding.
Test Behavior, Not Implementation
Ask “what should happen” rather than “how does it happen internally.”
// Good: tests the outcome
@Test
fun `an order fails when there isn't enough stock`() {
    inventory.setAvailable(productId, 3)

    val result = orders.placeOrder(buildPlaceOrderRequest(productId, quantity = 5), aCustomer)

    assertThat(result.getError()).isEqualTo(OrderError.OutOfStock(setOf(productId)))
}

// Brittle: tests the mechanics
@Test
fun `placeOrder calls pricing then inventory then repository`() {
    orders.placeOrder(request, aCustomer)

    inOrder(pricing, inventory, repository).apply {
        verify(pricing).priceLine(any())
        verify(inventory).reserve(any(), any(), any())
        verify(repository).save(any())
    }
}
The first test survives refactoring. Reorder the internal calls, add caching, change how you publish events: the test still passes because the behavior is the same. The second test breaks the moment you touch the implementation, even if nothing is actually wrong.
Don’t chase coverage numbers. A codebase with 70% coverage and thoughtful tests beats one with 95% coverage and useless tests. Coverage tells you what code ran, not whether your tests would catch a bug.
Part 10: Putting It All Together
How does all of this become a running application? More simply than you might expect: one application module pulls in the implementations, Spring wires them together, and you deploy a single JAR.
The Application Module
The application module is the composition root: the place where all the pieces come together. Its build.gradle.kts depends on all the -impl modules, and on the storefront:
// application/build.gradle.kts
dependencies {
    implementation(project(":products:products-impl"))
    implementation(project(":users:users-impl"))
    implementation(project(":payment:payment-impl"))
    implementation(project(":inventory:inventory-impl"))
    implementation(project(":orders:orders-impl"))
    implementation(project(":shipping:shipping-impl"))
    implementation(project(":storefront"))

    // Spring Boot, security, database drivers, etc.
    implementation("org.springframework.boot:spring-boot-starter-webmvc")
    implementation("org.springframework.boot:spring-boot-starter-security")
    implementation("org.postgresql:postgresql")
}
This is the only place that depends on -impl modules. Everyone else depends on -api modules. The application module breaks that rule because its job is to assemble everything. It’s also where the things that belong to the whole application live: security configuration (Part 8), the database connection, the executor for async listeners.
The application class itself is just a standard Spring Boot entry point:
@SpringBootApplication(scanBasePackages = ["com.example.shop"])
class Application

fun main(args: Array<String>) {
    runApplication<Application>(*args)
}
The scanBasePackages needs to cover your root namespace so Spring discovers components in all your -impl modules.
How Spring Wires It
Spring doesn’t care about Gradle modules; it cares about the classpath. At startup all the -impl modules are on it, so Spring finds ProductService, registers it as the bean for ProductApi, and injects it wherever another module asks for one. The interface is public and the implementation internal, and at runtime they meet in one application context. No service discovery, no HTTP clients, no serialization. Just dependency injection.
Project Structure
The overall structure follows naturally from what we’ve covered:
project-root/
├── build-logic/                    # Shared Gradle conventions
│   └── src/main/kotlin/
│       └── kotlin-conventions.gradle.kts
├── common/
│   ├── common-types/               # Shared kernel: Money, Email
│   └── common-result/              # Result type
├── products/
│   ├── products-api/
│   └── products-impl/
├── users/
├── payment/
├── inventory/
├── orders/
├── shipping/                       # ...each with -api and -impl
├── storefront/                     # Pages that combine modules
├── application/                    # Composition root
└── settings.gradle.kts
The common modules are the one place every module may depend on, which is exactly why they need a strict rule. Part 2 warned against a common module full of everyone’s ID types; this is a different thing. What belongs here is a shared kernel: a handful of types that mean the same thing in every context and almost never change. Money, Email, the Result setup. No business logic, no types owned by one module (the UserId lives in users-api, because Users owns it), nothing with a “for now” in its commit message. A good sign: changes to common are rare enough that each one gets a real discussion. If it changes every sprint, something in it belongs to a module.
The rest is ordinary Gradle and Spring Boot: convention plugins in build-logic keep every module’s build file short, and ./gradlew :application:bootJar packages all modules into one executable JAR.
One Process, Many Modules
One deployable means one thing to monitor at 3am. It also means one thing that falls over. The module boundaries protect you at compile time; at runtime, everything shares the same heap, the same threads and the same connection pool. A memory leak in one module or a slow query in another can take down checkout.
A few habits keep a module’s runtime trouble its own:
- Know which module you’re looking at. Put the module name in your logs and metrics, so “the app is slow” becomes “Inventory’s queries are slow”. Spring Modulith’s observability support does this for you: it creates a tracing span whenever a call crosses into another module.
- Give async work its own pools. If every
@ApplicationModuleListenerruns on one shared executor, one module’s slow listener queues up everyone else’s events. Separate executors for the modules that do heavy work keep the rest moving. - Put limits on the shared things. Statement timeouts on the database, sensible pool sizes, timeouts on outbound HTTP calls. In a monolith, an unbounded wait in one module is everyone’s wait.
- Remember there’s more than one of you. Run two instances for availability and every
@Scheduledjob runs twice. The guarded transitions from Part 6 make that harmless; anything that isn’t guarded needs a lock (ShedLock is the usual choice).
When You Outgrow It
The architecture is designed to be “split-ready”, even if you never split.
If a module eventually needs to become a separate service, most of the work is already done. The database is isolated: each module has its own schema and its own role, so you move it to a new database without untangling shared tables. The API is defined: the -api module becomes the contract for the new service. The tests are structured: the contract tests from Part 9 can run against the remote client too. And the events already go through an outbox; mark them @Externalized, and Spring Modulith sends them to Kafka or RabbitMQ from the same table.
You’re not refactoring a tangled mess. You’re promoting a module that’s already isolated.
But don’t mistake split-ready for free. Swapping dependency injection for an HTTP client changes what a call means:
- Calls can fail halfway. An in-process call either happens or throws. A network call can time out after the other side did the work. Your
Resulttypes modelNotFound; now they also need “unavailable” and “unknown”, and retries need idempotency. - Chatty becomes slow. The batched calls from Part 4 are fine in-process. Over a network, every round trip costs milliseconds, and a page that makes fifty calls takes a second.
- Shared transactions disappear. Any place where two modules relied on one database transaction (Part 5) now needs an event, a process (Part 6) or a rethink. This is why it pays to avoid them from the start.
Most teams never need to. A modular monolith scales further than people expect, both technically and organizationally. But knowing the escape hatch exists makes the choice less risky: you’re choosing the simplest architecture that works today, while keeping your options open.
Part 11: One Domain, Several Products
So far, the shop has been one product. That’s where most examples stop, and it’s where real systems tend to get interesting.
Two years in, the warehouse and the deliveries are the best thing the company has. So it launches a second product: a fulfilment service for other webshops. They store their stock in our warehouse; their customers’ orders come in through a plugin in their own webshop; we pick, pack and ship, and charge them once a month. Meanwhile, the shop has started selling products from independent makers alongside its own, and pays the makers out once a month.
So now there are two products. Each has its own customers, its own way of selling (a checkout here, an order plugin there) and its own onboarding. Both onboard sellers, makers in one and merchants in the other, and each seller has a wallet at the payment provider. And underneath both, the work is the same: the same warehouse, the same stock counts, the same parcels, the same monthly settlement.
Build that twice and the two copies drift apart within a year. Share it naively and the shared part ends up full of if (product == SHOP). This part is about the third option.
The Domain Gets Its Own Language
The shared work becomes a domain of its own: fulfilment. It’s a group of modules (Inventory, Shipping, a new Settlement module, and a small Parties module for who’s who) used by both products.
The first thing to go is everything the shared domain knew about the shop. Inventory depended on the shop’s Products for its ProductId; Shipping listened to the shop’s OrderConfirmedEvent. Neither can stay: a shared domain that depends on one product isn’t shared. So it gets words of its own, for what it deals with:
- a party: someone whose goods we hold and who gets settled, with a wallet;
- an item: something on a shelf, with a SKU, an owner, a size and a weight;
- a shipment: a parcel to send, for some party, to some address.
The products translate into these words, the way Orders translated ProductDto into its own OrderLine in Part 5. The shop’s catalog keeps its products and points at the domain’s items; the fulfilment service’s merchants become parties. The domain never learns what a maker or a merchant is.
The domain’s inner modules keep the rules from Part 2 among themselves: their own -api and -impl, their own schemas, a one-way graph with Parties at the bottom. Don’t put a facade over the whole group just so it has one front door. Do decide which of its -api modules are for the products and which are only for the domain’s own modules, and let the validation task enforce it.
Notice what happened to the dashed arrow from Part 2, where Orders listened to Shipping’s events. It’s gone. Shipping is below both products now, so when the shop’s Orders listens for a delivery, it’s listening down. Making the domain reusable fixed the one place where the graph bent.
Push What It Must Keep, Ask What It Doesn’t Own
The question in every shared domain is how it gets data from products it isn’t allowed to know. There are two directions, and choosing the right one for each piece of data is most of the design:
| The domain needs… | For example | How it gets it |
|---|---|---|
| facts it has to keep and calculate with | a parcel to send, a sale to settle | the product pushes them in through the domain’s API, when they happen |
| a product’s rule, inside the domain’s calculation | what a parcel costs this product’s sellers | the domain asks through an SPI the product implements |
| to know who someone is | which wallet a seller is settled on | the product registers them once, when it onboards them |
Facts are pushed, and the domain keeps its own copy. A statement has to add up in March and still add up in October, when a seller disputes it. If the domain had to ask the products for March’s sales again, it would be relying on their data not having changed since. So the products hand facts over as they happen, and the domain stores them in its own terms. It’s the “copy at write time” from Part 4, at the scale of a whole domain:
// the shop, when a maker is onboarded
val party = parties.register(
    scope = ProductScope("shop"),
    reference = PartyReference(maker.id.value),  // the shop's own ID: handed back in questions
    wallet = maker.walletId,                     // from payment-api, which both sides know
)

// the shop's Orders, when an order is confirmed: a listener that calls one command (Part 6)
shipping.requestShipment(
    ShipmentRequest(
        reference = ShipmentReference(order.id.value),
        sender = order.sellerParty,
        lines = order.lines.map { ShipmentLine(it.sku, it.quantity) },
        address = order.shippingAddress,
    )
)
The fulfilment service’s order intake makes exactly the same calls, from a webhook instead of a checkout. Shipping can’t tell the difference, and that’s the point.
Rules are asked for, and the answer is stored. What does a parcel cost? That’s commercial, and it differs per product: the fulfilment service charges merchants per parcel, and the shop ships makers’ parcels for free and takes a commission instead. If the domain knew those prices, it would know the products. So Settlement asks:
// settlement-api/spi
interface PriceList {
    val scope: ProductScope
    fun price(charge: Charge): Money
}

sealed interface Charge {
    data class ParcelShipped(val party: PartyReference, val weightGrams: Int, val country: CountryCode) : Charge
    data class StorageUsed(val party: PartyReference, val cubicMetreDays: BigDecimal) : Charge
}
Each product implements it, as a bean in its own modules, and Settlement sends each question to the price list of the party’s product. A product without one fails loudly. The answer goes onto the statement line straight away, with the charge it priced. When a product changes its prices in May, April’s statement doesn’t change. Asking for a rule doesn’t mean asking for it again later.
Products add their own lines. Some money is purely a product’s business: what a maker earns from a sale, and the shop’s commission on it. The shop pushes those as lines of its own. Settlement doesn’t care where a line comes from; it adds up lines per party, per month:
// settlement-api
data class SettlementLine(
    val id: LineId,               // chosen by the caller: adding a line twice adds it once
    val party: PartyId,
    val amount: Money,            // positive: we owe them; negative: they owe us
    val description: String,
    val source: LineReference,    // what it's for, in the caller's terms
)
Products Are Scopes, Not Branches
Both products run against the same warehouse, so in this example the domain runs once, in one deployment, and every party belongs to a product. That’s the ProductScope above: a plain value the domain defines and the product chooses.
The domain may carry the scope, store it, filter by it and route SPIs by it. It never branches on its value. The moment if (party.scope == ProductScope("shop")) appears in the domain, the domain knows about the shop again, and the third product will need a third branch. Whatever differs per product belongs behind an SPI the product implements, or in lines the product pushes.
Whether you need scopes at all depends on one question: does the domain own something the products share in the real world? Here it does: one warehouse, one stock count, parcels on the same truck. So it runs once, with scopes. If each product’s data would be separate anyway, there’s a simpler option: each product’s application module includes its own copy of the domain modules, with its own database, and the scope disappears.
Settling on the Wallets
Closing the month is a process (Part 6) with a statement as its subject: open, then closed, then paid.
// settlement-impl
@Scheduled(cron = "0 0 3 1 * *")  // the first of the month, at three
fun closeLastMonth() {
    statements.findOpen(period = YearMonth.now(clock).minusMonths(1))
        .forEach { statements.close(it) }  // final from here; publishes StatementClosedEvent
}

@ApplicationModuleListener
fun on(event: StatementClosedEvent) {
    payments.transfer(event.wallet, event.total, PaymentReference(event.statementId.value))
}
Settlement uses Payment directly: Payment is a foundation that knows nothing about statements, and the transfer is idempotent on its reference, so a redelivered event pays once. That works because both products settle the same way, on wallets at the same provider. If one product paid out by bank transfer and the other sent invoices, settlement would stop at the closed statement and publish it, and each product would collect or pay in its own way.
Late facts are the rule, not the exception. A return in April for a sale settled in March doesn’t reopen March. It becomes a new line in April’s statement, saying which line it corrects. Closed statements are never edited; that’s what makes them something you can send to a seller, and defend.
Owning a Shared Domain
A shared domain is a product with products for customers. That changes a few things.
- One team owns it, in the same repository as the products. The products ask for changes; the domain team decides how they fit its language, and
CODEOWNERSon its-apimodules makes that real. Don’t release it as a library to two other repositories: that means versions, upgrades and a product that’s always two releases behind. - Every change is checked against every user. In one repository, a change to the domain’s contract compiles against both products in the same build, and the contract tests run against both price lists. The domain ships fakes for the products’ tests (Part 9), and keeps a fake price list for its own.
- Its language is guarded. Words from one product creeping into the domain are the first sign of trouble: a
makerIdin a shipment, acommissionfield on a statement line. Review the domain’s contracts for product words the way you review code for bugs. - Screens go with the rules behind them, as with the storefront (Part 8). A statement or a seller’s stock shows the domain’s numbers and nothing else, so those screens are the domain’s; navigation, onboarding and branding are the product’s. Start with view models in the domain’s API and let each product build its own screen. Ship a shared component once a second product needs the same one, not before.
When Two Domains Meet: A Connector
So far, the domain has had products above it and Payment below it. Not every pair of domains stacks like that. Finance wants a proper invoice for every closed statement: numbered without gaps, with VAT, and in the books. That’s a domain of its own, Invoicing, and it invoices more than statements: the shop’s customers get their receipts from it too. Settlement has no business knowing what an invoice is, and Invoicing has no business knowing what a statement is. Yet one has to lead to the other.
Let either depend on the other and it learns the other’s words, and the graph gets an arrow that points sideways. Put the glue in the products and it’s written twice. What’s left is a small module in between: a connector. It depends on the -api modules of both domains, and neither domain depends on it or on the other.
It does for another domain what the products did above: it pushes facts in, in the receiving domain’s words. When a statement closes, it asks Parties who the party is and issues the invoice:
// settlement-invoicing: knows both contracts, and Parties'
@Component
internal class InvoiceClosedStatements(
    private val parties: PartiesApi,
    private val invoicing: InvoicingApi,
) {
    @ApplicationModuleListener
    fun on(event: StatementClosedEvent) {
        val party = parties.get(event.party)
        val request = InvoiceRequest(
            // one invoice, however often the event comes
            reference = InvoiceReference(event.statementId.value),
            // copied: the invoice keeps the address as it was
            billTo = BillingDetails(party.name, party.address, party.vatNumber),
            lines = event.lines.map { InvoiceLine(it.description, it.amount) },
        )
        invoicing.issue(request)
    }
}
It works the other way round too. If Invoicing needed to ask something while it works, it would declare an SPI in its own words, and the connector would implement it by calling the other domain’s API.
It’s the storefront from Part 8 again, for commands instead of pages, and it stays useful for the same reason: it stays thin.
- No rules of its own. It maps words and references and calls one command per event (Part 6). An
ifabout amounts, dates or statuses is a rule, and rules belong to one of the two domains. If one belongs to neither, you’ve found a third domain. A connector that collects logic becomes the place where rules hide from both domains. - No state of its own, except, if you must, a table that maps one side’s references to the other’s. Once it waits for answers, retries until a deadline or tracks how far it got, it’s a process, and a process lives with the thing it’s about.
- One connector per pair, named after both. A single “integration” module for everything gathers all the coupling in the system in one place.
- The build keeps the shape. The connector may depend on both contracts; the domains may not depend on each other, which
allowedDependenciesand the Gradle dependencies from Part 2 both check. - Test it as a translation. With the fakes each domain ships (Part 9) on both sides, one event goes in, and you check the command that comes out.
Don’t reach for one by default. When one domain is clearly below the other, depend downwards: Settlement uses Payment directly, and a connector between them would be a layer that buys nothing. When only one product combines two domains, that product is the connector, as in the rest of this part. A connector earns its place when the pairing is the same whichever product a fact came from, as here: every closed statement gets an invoice.
Part 12: Building With Coding Agents
A growing share of the code in a codebase like this is now written by coding agents: Claude Code, Codex, Cursor and the like. That changes the cost-benefit sums of a modular monolith, mostly in its favor. Everything in this guide that helps a new team member also helps an agent, only more so. An agent starts every task as a new team member.
A Module Fits in a Context Window
An agent can only reason about what it has read, and reading costs context. In a tangled codebase, “add discount codes to orders” means reading half the system to find out what might break. In a modular monolith, the task has a natural scope: orders-impl, plus the -api modules Orders depends on.
Those -api modules are a compact map of the whole system. Every capability, every DTO, every event and every error type, without a line of implementation. An agent can read the APIs of all six modules in a few thousand tokens and know what the rest of the system can do for it, without guessing.
Microservices give you small scopes too, but they hide the neighbors behind a network: the agent sees an HTTP client and has to guess what the other side does. In a monolith, the contract is right there in the repository, and the compiler checks it.
The Build Is the Reviewer
Agents take the same shortcuts as a developer on a deadline, only faster and more often. The test needs a product, and there’s a perfectly good builder in products-impl. The query needs a product name, and the products table is right there.
This is where enforcement pays off twice. A rule in a wiki page gets broken; a rule in the build gets followed, because the agent sees the failure and fixes it in the same loop, before a human ever looks. Every check in this guide becomes feedback an agent can act on:
- an import from another module’s
-impl: a compile error; - an upward dependency or a test fixture crossing a boundary: a failed module validation task;
- a join into another module’s schema: “permission denied” in the module tests;
- a fake that drifted from the real implementation: a failed contract test;
- a new order status nobody handled: a
whenthat no longer compiles.
The faster those checks run, the more useful they are. Make sure every module can be verified on its own, so an agent working in Shipping runs ./gradlew :shipping:shipping-impl:check in seconds instead of the whole suite in minutes.
One thing to guard: an agent that can’t get past a failing check may “fix” the check. It adds products-impl to the dependencies, or loosens the validation rule. Keep the rules in build-logic, put the build files and the module validation config under CODEOWNERS, and tell your agents explicitly that changing dependencies between modules is a question for a human, not a fix.
Write It Down, for Both Readers
Good documentation used to be a courtesy to the next developer. Now every agent reads it on every task, so it pays twice. Make it a rule: anything someone on the team can answer, an agent can answer too, from the repository. The architecture rules, the coding guidelines, how to build and test, why a decision went the way it did, how a third party’s API behaves and how we integrate with it. If the answer only lives in someone’s head or in a chat thread, the agent guesses, and it guesses confidently.
Most agents read instruction files from the repository (AGENTS.md, CLAUDE.md). Put one at the root with the architecture rules and the commands (the cheat sheet at the end of this guide is plain text for exactly that reason), and a short one in each module with what only that module knows:
# Orders

Owns orders and checkout, from placed to delivered.

- Public contract: `orders-api`. Changing it needs review from the Orders team.
- Checkout is the order's status: AWAITING_PAYMENT → CONFIRMED → DELIVERED, or CANCELLED.
  Every listener checks the status before it acts.
- A listener changes an order or calls one command on another module, never both.
- Publishes: OrderConfirmedEvent, OrderCancelledEvent.
- Listens to: PaymentCompletedEvent, ShipmentDeliveredEvent.
- An order's lines are fixed once it is placed.
- Test: ./gradlew :orders:orders-impl:check
Keep it short and keep it true. The structure of the code already says most of it; the file is for the invariants and decisions that the code can’t show. Longer reference material, like the payment provider’s integration guide, goes in a document or a skill that’s loaded only when a task needs it, so it doesn’t crowd every other task. Claude Code’s guide to large codebases shows how to layer instruction files and skills per directory.
Give Agents Your Tools
An agent can only use what it can reach. One that reads the pull request through the gh CLI and fetches the story from Jira reviews a change against what was asked for. One that only sees the diff can only review the code. Give agents the tools you’d use for the same task: the command-line tools for your Git host and issue tracker, a way to start the module’s tests, the logs of a test environment. Read access is usually enough, and safer. Claude Code best practices has more on setting this up.
Then tell them to use it. Anthropic’s prompting guide for Claude Opus 5.5 found that agents got noticeably more tasks right when told to look through every relevant source before acting, including the ones the task doesn’t mention.
A Review Skill That Keeps the Docs True
Documentation goes stale one pull request at a time, so keep it up to date in the same place. Write your review as a skill: instructions an agent loads when it’s asked to review a pull request. Let it look at the change from each angle this guide cares about, and finish by updating the documentation:
---
name: review-pr
description: Review a pull request against our architecture, tests and docs. Use when asked to review a PR.
---

1. Read the PR (`gh pr view`, `gh pr diff`) and the story it links to.
   Does it do what the story asks, and nothing else?
2. Boundaries: a new dependency between modules, or a change to an `-api` module,
   an event or an error type? Flag it for a human.
3. Data: migrations expand, then contract. No queries into another module's schema.
4. Processes: listeners check the status first, and change their own module
   or call one command.
5. Tests: module tests cover the behavior, including what goes wrong.
6. Docs: update the AGENTS.md of every module the PR changes, and any integration
   docs it affects, in the same PR.
Run it in a fresh session, not the one that wrote the code: an agent reviewing its own work in the same context tends to agree with itself. And the last step is what keeps the rest working. Every pull request leaves the documentation as true as the code, so the next agent, and the next person, starts from something it can trust.
Where Humans Look
With agents writing more of the code, review attention becomes the scarce resource, and the module structure tells you where to spend it. A change inside one -impl module is contained: if it’s wrong, it’s wrong in one place, and the module tests say so. Changes to the seams are different. A new method or error in an -api module, a new event, a database migration, a new dependency between modules, a new step in a process: those shape everyone else’s code, and they’re worth a careful human read.
The same seams make it practical to run several agents at once. Two agents working in Shipping and Inventory rarely touch the same files, so their work merges cleanly. When both need a change to the same -api, that’s your signal to coordinate first.
And the oldest objection to all this structure, the ceremony, has largely gone away. An -api module, a mapper, a DTO and a fake are tedious to write by hand and trivial for an agent. The boilerplate is cheap now. The boundaries are what it buys you.
Conclusion
A modular monolith isn’t a compromise or a stepping stone to microservices. For most teams, it’s the destination.
You get boundaries that hold, because the build enforces them. Changes stay local, because modules can’t reach into each other’s code or tables. Processes survive a failure halfway, and a second product can share the domain without bending it. And you still deploy one JAR, with one thing to monitor at 3am.
The real payoff is that a mess stays contained. In a traditional monolith, every shortcut becomes everyone’s problem. In a modular monolith, a messy module is just a messy module: clean it up later, on your own schedule. That pays off even more now that agents write a growing part of the code, because the rules the build enforces are the ones that actually get followed.
Build the boundaries. Enforce them. Ship the JAR.
Cheat Sheet
Five ideas hold everything else up. The cards after them show how the ideas play out in each area. It’s all plain text, so you can paste it into your AGENTS.md.
The five that matter most
- Draw modules around what the business does (orders, inventory, shipping), not around technical layers. Every piece of data has exactly one owner: the module that may change it.
- Keep dependencies between modules one-way, and let the build enforce it. A module sees only another module's contract, never its implementation.
- Each module owns its data: its own database schema, with no shared tables, joins or foreign keys across modules.
- Work that spans modules goes through events that can't get lost: stored in the same transaction as the data (an outbox). Each transaction changes one module.
- Contracts say what can go wrong. Expected errors are values in a module's API, not exceptions.
- Unsure if it's one module or two? Make it one. Splitting later is cheap; merging isn't.
- A field belongs to the module whose rules depend on it, not the one that displays it.
- Each module has its own model of a shared word: the catalog's "product" isn't the warehouse's.
- Publish only what other modules use. Rules and behavior stay internal.
- A module only defines types it owns. It points at another module's things by their ID, if it already depends on that module. If that module sits above it, it uses a reference type of its own, so it doesn't have to depend upwards.
- When a lower module needs an answer from a higher one, it defines an interface for the question, and the higher one implements it.
- Short lists from another module: fetch them in one batch and combine in memory.
- Sorting or paging by another module's data: keep a local copy, updated from its events.
- What must stay as it was, like the price at purchase: copy it when you write.
- Change a schema in two deploys: add the new, then remove the old.
- Call another module when you need an answer now. Publish an event to say something happened.
- Every listener copes with getting the same event twice.
- Stored events are contracts: add fields, never rename or remove them.
- A process across modules is the status of what it's about (an order), checked before every step.
- Hold stock with a reservation that expires, instead of checking and hoping.
- A listener changes its own module or calls one other module, never both.
- Undoing is a new operation, like a refund. Do what's hardest to undo last.
- Log users in once, at the edge, and pass the user ID into modules explicitly.
- Role checks go on the endpoint; "whose record is this" goes with the data.
- A page that needs several modules gets a thin module of its own that only asks and assembles.
- Clients you don't deploy yourself get versioned API models of their own.
- A domain used by several products speaks its own language and knows nothing about them.
- Products push in the facts it must keep. For a product's own rule, the domain asks through an interface the product implements.
- Everything carries which product it belongs to, but the domain never branches on it.
- Two domains that mustn't know each other meet in a thin connector that only translates.
- Test each module for real, on a real database, with fakes for the modules it uses.
- A module ships the fake of itself, and a shared contract test keeps fake and real in step.
- Test outcomes, not which methods were called.
- Every module can be checked on its own, in seconds.
- Changing dependencies between modules is a human's decision, never an agent's fix.
- Anything someone on the team can answer, an agent can answer from the repository.
- Give agents the tools you use: the pull request, the story, the logs.
- A review skill checks every pull request and updates the docs in it.